I've spent the last year or so reviewing Gene Kim's new book - the Phoenix Project and encouraging him to get it finished. It came out this week, is the top business book on Amazon as I write this, and I got a nice back-cover quote shown below with Gene's actual finger in the photo.
Many years ago someone gave me a copy of The Goal, which is the inspiration for The Phoenix Project. In both cases the book is a novel about a company that is dysfunctional and on the verge of going out of business. The lead character is dropped into the job of figuring out how to dig their way out of the problem, and in the case of The Phoenix Project, the company fumbles its way from legacy enterprise where IT isn't regarded as central to their success, into the modern world of agile development practices and DevOps deployments where IT becomes a competitive advantage.
Don't just read it, give copies of it to your friends in management. It should be on every CxO's bookshelf.
Wednesday, January 16, 2013
Tuesday, January 01, 2013
Looking back at 2012, with pointers to 2013
A collection of things that seem to have pivoted in 2012.
This is one of those pivotal changes, similar to the change from having predominantly fixed wire telephone service at home, to having many people use mobile phones exclusively. It costs more, but if you already have a high bandwidth connection to your phone with a high data cap because you use it a lot, why pay to also have a low bandwidth connection to your house? Bandwidth caps and data usage plans will slow the switchover, but the writing is on the wall.
The TV has an AppleTV connected to it, which gets almost all the usage. We watch a few things on laptops, and sometimes I connect a laptop to the TV. I also stream music from my iPhone to the AppleTV because I can't get Pandora or Spotify on it. Come on Apple, where's the AppleTV App Store? Maybe that's a 2013 thing.
The Enterprise Computing vendors haven't been able to build a public cloud that competes with AWS on scale, price or features, and AWS is now focused on building everything their customers need to take the next generation of application investment out of the datacenter, so the high margin revenue is going to gradually go away for the traditional vendors.
The most interesting development in 2012 was the re-launch of Google as a public cloud infrastructure vendor, and the mini-price-war between AWS and Google over instance and storage costs makes it clear where the real action is. During 2013 we will see if Google manages to invest heavily and execute well enough to build up a big user base. In mobile, as I predicted years ago, we are now in an iPhone vs. Android battle that is wiping out everyone else. I personally think in 2014 we will likely see a similar effect as the scale, features and price point of AWS and Google clouds make everyone else irrelevant. The only question in my mind is whether AWS runs away with this on their own, or Google manages to get some traction as the alternative.
Note to sales reps (who won't listen), I'm not interested in anything to do with datacenters, private cloud, or other public clouds in 2013. I'm only interested in SaaS apps, things that run on AWS, and interesting open source projects.
A friend recently got a quote for Solar Power installation which was about half what we paid two years ago, and we got a good deal then. Prices have dropped fast and are much lower than most people think. If you don't already have solar panels on your roof, you should get them. If you don't use enough electricity to justify solar panels, get an electric car as well, and save at the gas pump.
The Republican party is still in denial, a combination of funding from big oil companies and an inability to accept or admit that their demonized Al Gore could have been right all along. In 2013 it will be interesting to see how they deal with losing the election, and perhaps there will be a split into a group of Republicans that see the path to re-election in 2014 as needing to accept reality by voting for some Global Warming related legislation, versus the hard core that are trying to pray their way out. The current battle is over stopping the Keystone XL pipeline that would move the dirtiest kind of tar oil from Alberta Canada to Texas. It may be symbolic, but if KXL is stopped, the tide will have turned. Carbon needs to be left in the ground. For 2013, I'm going to try and re-balance my 401K retirement accounts to divest from oil companies. Many students are now pressuring their colleges to divest from oil as well.
Mobile Bandwidth Greater than Fixed Bandwidth
I've been talking about LTE and the growth in mobile since 2008, but I started 2012 with a Verizon iPhone 4 which maxed out at 2Mbit/s over 3G and at home in the mountains I would get less than 1Mbit/s. I ended 2012 with a Verizon iPhone 5 which is about ten times faster at home, I regularly see 8-9Mbits/s, and the best speed I have seen anywhere so far was in downtown Los Gatos at over 50Mbit/s. My home fixed wire Internet is a 3Mbit/s DSL that has neighborhood congestion at peak times. I now find it works better to have WiFi turned off on my iPhone at home.This is one of those pivotal changes, similar to the change from having predominantly fixed wire telephone service at home, to having many people use mobile phones exclusively. It costs more, but if you already have a high bandwidth connection to your phone with a high data cap because you use it a lot, why pay to also have a low bandwidth connection to your house? Bandwidth caps and data usage plans will slow the switchover, but the writing is on the wall.
Cutting The Cable/Satellite TV Feed
In 2013 we finally turned off our TiVo and shut down our DirecTV account. We weren't using it enough to make it worth while. For some of the sports events (Laurel follows the Stanford Cardinals), we go to a sports bar to watch, which is more fun anyway. Everything else that we have time to watch, we can watch online, and we get all our news updates from Twitter, RSS feeds and Facebook posts. By the time it's on TV or in a newspaper, it's already old news.The TV has an AppleTV connected to it, which gets almost all the usage. We watch a few things on laptops, and sometimes I connect a laptop to the TV. I also stream music from my iPhone to the AppleTV because I can't get Pandora or Spotify on it. Come on Apple, where's the AppleTV App Store? Maybe that's a 2013 thing.
The Netflix Open Source Cloud Platform Got Traction
We started the year with a handful of disconnected projects, and ended it with a large chunk of the platform on Github, and some high profile users. Most people are still picking it up piecemeal but in 2013 we plan to get the whole thing put together as an installable bundle. This is the Alan Kay approach, "The best way to predict the future is to invent it". Netflix has been out in front of the industry in terms of cloud adoption, inventing the future. Next we make it easier for others to join us in that future, and have some ideas for how to drive adoption to new heights.Netflix Cloud Architecture Presentations
I was going to list all the talks I gave, but there are too many, so go see the slides I posted at http://www.slideshare.net/adrianco. Highlights were QConSF, QConLondon, Gluecon in Colorado, GOTO in Aarhus and of course AWS Re:Invent in Las Vegas. The impact of these talks grew through the year, reaching a peak at Re:Invent, where we had lots of speakers and attention to the way the Netflix cloud and open source story was bringing value to the company and reaching out into the technical community. A big thanks to everyone who came to my talks, and all the other Netflix speakers who have been out there broadening the story. It's almost impossible to write an article or do a presentation about cloud without mentioning Netflix. In 2013 there will be even more talks, I focus on local and US based events that are strongly developer oriented like QCon, Gluecon, and GOTO. We will definitely be back at AWS Re:Invent next November.The Concept of Anti-Fragility Took Off
Nassim Taleb's latest book crystallizes the way I tend to approach things and gives it a name. The Netflix cloud architecture is anti-fragile, we run "Chaos Monkey's" continuously to try and break it, and that makes it stronger. The Netflix culture is anti-fragile, it's decentralized with as little process and rules as possible and a lot of local autonomy. Netflix management is not afraid of change or of being first to do something and tends to navigate disruptive transitions well. From the outside this can look chaotic or confusing, but it works, and recovers well from missteps, which are always going to happen. If you're not failing occasionally you aren't trying hard enough, and you are missing opportunities. Getting stronger through failure is the basis of anti-fragility. Avoiding failure at all costs (as many people try to do) makes you brittle and vulnerable to unexpected Black Swan events that will have a much bigger impact.Cloud, Open Source, SaaS and the End of Enterprise Computing
Taleb makes the point that big companies become increasingly fragile as they lose agility and the ability to move with the markets, and we are seeing that play out in the Enterprise Computing space. There is still money to be made from the late adopter customers, but the trend is clearly towards development using exclusively open source tools, with applications and infrastructure delivered as a service. There is zero revenue for traditional Enterprise Computing vendors in this model. The current interest in building out private cloud infrastructure is real and will continue to support traditional vendors into 2013, but it's a short term investment. At best you end up with a much better automated datacenter, but it isn't elastic and it has far fewer features than AWS, so it's going to be marginalized over time. At worst, you discover just how hard it is to run a reliable private cloud based on immature software, with incompatible upgrade paths, and it turns out to be much more expensive to run.The Enterprise Computing vendors haven't been able to build a public cloud that competes with AWS on scale, price or features, and AWS is now focused on building everything their customers need to take the next generation of application investment out of the datacenter, so the high margin revenue is going to gradually go away for the traditional vendors.
The most interesting development in 2012 was the re-launch of Google as a public cloud infrastructure vendor, and the mini-price-war between AWS and Google over instance and storage costs makes it clear where the real action is. During 2013 we will see if Google manages to invest heavily and execute well enough to build up a big user base. In mobile, as I predicted years ago, we are now in an iPhone vs. Android battle that is wiping out everyone else. I personally think in 2014 we will likely see a similar effect as the scale, features and price point of AWS and Google clouds make everyone else irrelevant. The only question in my mind is whether AWS runs away with this on their own, or Google manages to get some traction as the alternative.
Note to sales reps (who won't listen), I'm not interested in anything to do with datacenters, private cloud, or other public clouds in 2013. I'm only interested in SaaS apps, things that run on AWS, and interesting open source projects.
Solar Powered Electrics Cars Are For Real Now
We drive our Nissan Leaf all the time, it's fun to drive and the first car we pick for most trips, adding up to almost 1000 miles a month. The marginal cost of running the car is near zero. New tires and a cabin air filter at 15K miles is all the maintenance it needs. We have an excess of solar power generation that added up to $500 in unused electricity over the year. At 10c/KWh and 3.5KWh/mile that's plenty for us run a second electric car before we start paying for the power, and there are a lot more choices coming in 2013. There are many charging stations around the Bay Area, lots of other people running Leafs, and the Tesla Model S got car of the year awards. It takes a test drive to realize what fun it is to have instant torque and no gear shifts. This is a case of the future being unevenly distributed. If you don't live in California, it's a bit further out, but it's coming.A friend recently got a quote for Solar Power installation which was about half what we paid two years ago, and we got a good deal then. Prices have dropped fast and are much lower than most people think. If you don't already have solar panels on your roof, you should get them. If you don't use enough electricity to justify solar panels, get an electric car as well, and save at the gas pump.
Global Warming Arrived in the USA in 2012
The well funded Merchants of Doubt (read the book) managed to confuse and suppress public discussion of global warming in the USA for the last few years, but the effects just became too obvious this year and it broke through, creating the scenarios that James Hansen warned of in Storms of My Grandchildren. The arctic ice cap melt continues to accelerate, seas are warming and rising, drought and record heat hit most of the USA, and everything wrapped up with Hurricane Sandy, pushing the topic onto the front page. The dice are all loaded now, and 2013 is already rolling those dice as the drought continues and the Mississippi river is empty. I've been saying for the last few years that if you own property at sea level, you should find someone who doesn't believe in global warming to sell it to, because it's going to become increasingly uninsurable and end up as worthless as the houses along the New Jersey shoreline that were swept away.The Republican party is still in denial, a combination of funding from big oil companies and an inability to accept or admit that their demonized Al Gore could have been right all along. In 2013 it will be interesting to see how they deal with losing the election, and perhaps there will be a split into a group of Republicans that see the path to re-election in 2014 as needing to accept reality by voting for some Global Warming related legislation, versus the hard core that are trying to pray their way out. The current battle is over stopping the Keystone XL pipeline that would move the dirtiest kind of tar oil from Alberta Canada to Texas. It may be symbolic, but if KXL is stopped, the tide will have turned. Carbon needs to be left in the ground. For 2013, I'm going to try and re-balance my 401K retirement accounts to divest from oil companies. Many students are now pressuring their colleges to divest from oil as well.
Twitter and Snapchat
Personally, 2012 was an excellent year for me, I've made lots of new friends and learned a lot by being active on twitter, ending the year with about 6500 followers. I joked on twitter that I posted my new years resolutions for 2013 to Snapchat, but you missed them. If you don't know what Snapchat is for, ask a teenager. You'll probably hear a lot more about it in 2013, then, when their parents figure it out and join too, the teens will be onto the next thing....
Labels:
2012,
2013,
anti fragile,
AppleTV,
global warming,
gluecon,
google,
goto,
iPhone,
qcon,
Solar power,
was
Monday, November 26, 2012
Lots of Netflix talks at AWS Re:Invent
[Update: here's video's of these talks http://techblog.netflix.com/2012/12/videos-of-netflix-talks-at-aws-reinvent.html along with slides]
There is a Netflix booth in the expo center, we will be talking about our open source tools from http://netflix.github.com and collecting resumes from anyone interested in joining us.
Date/Time
|
Presenter
|
Topic
|
Wed 8:30-10:00
|
Reed Hastings
|
Keynote with Andy
Jassy
|
Wed 1:00-1:45
|
Coburn Watson
|
Optimizing
Costs with AWS
|
Wed 2:05-2:55
|
Kevin McEntee
|
Netflix’s Transcoding
Transformation
|
Wed 3:25-4:15
|
Neil Hunt / Yury I.
|
Netflix:
Embracing the Cloud
|
Wed 4:30-5:20
|
Adrian Cockcroft
|
High Availability Architecture at
Netflix
|
Thu 10:30-11:20
|
Jeremy Edberg
|
Rainmakers – Operating Clouds
|
Thu 11:35-12:25
|
Kurt Brown
|
Data Science
with Elastic Map Reduce (EMR)
|
Thu 11:35-12:25
|
Jason Chan
|
Security Panel: Learn from
CISOs working with AWS
|
Thu 3:00-3:50
|
Adrian Cockcroft
|
Compute & Networking
Masters Customer Panel
|
Thu 3:00-3:50
|
Ruslan M./Gregg U.
|
Optimizing Your Cassandra
Database on
AWS
|
Thu 4:05-4:55
|
Ariel Tseitlin
|
Intro to
Chaos Monkey and the Simian Army
|
Friday, November 16, 2012
Cloud Outage Reports
The detailed summaries of outages from cloud vendors are comprehensive and the response to each highlights many lessons in how to build robust distributed systems. For outages that significantly affected Netflix, the Netflix techblog report gives insight into how to effectively build reliable services on top of AWS. I've included some Google and Azure outages here because they illustrate different failure modes that should be taken into account. Recent AWS and Azure outage reports have far more detail than Google outage reports.
I plan to collect reports here over time, and welcome links to other write-ups of outages and how to survive them. My naming convention is {vendor} {primary scope} {cause}. The scope may be global, a specific region, or a zone in the region. In some cases there are secondary impacts with a wider scope but shorter duration such as regional control planes becoming unavailable for a short time during a zone outage.
This post was written while researching my AWS Re:Invent talk.
Slides: http://www.slideshare.net/AmazonWebServices/arc203-netflixha
Video: http://www.youtube.com/watch?v=dekV3Oq7pH8
November 18th, 2014 - Azure Global Storage Outage
Microsoft Reports
http://azure.microsoft.com/blog/2014/11/19/update-on-azure-storage-service-interruption/
http://azure.microsoft.com/blog/2014/12/17/final-root-cause-analysis-and-improvement-areas-nov-18-azure-storage-service-interruption/
January 10th, 2014 - Dropbox Global Outage
Dropbox Report
April 20th, 2013 - Google Global API Outage
Google Report
February 22nd, 2013 - Azure Global Outage Cert Expiry
Azure Report
December 24th, 2012 - AWS US-East Partial Regional ELB State Overwritten
AWS Service Event Report
http://aws.amazon.com/message/680587/Netflix Techblog Report
http://techblog.netflix.com/2012/12/a-closer-look-at-christmas-eve-outage.htmlOctober 26th, 2012 - Google AppEngine Network Router Overload
Google Outage Report
October 22, 2012 - AWS US-East Zone EBS Data Collector Bug
AWS Outage Report
Netflix Techblog Report
June 29th 2012 - AWS US-East Zone Power Outage During Storm
AWS Outage Report
Netflix Techblog Report
June 13th, 2012 - AWS US-East SimpleDB Region Outage
AWS Outage Report
February 29th, 2012 - Microsoft Azure Global Leap-Year Outage
Azure Outage Report
August 17th, 2011 - AWS EU-West Zone Power Outage
AWS Outage Report
April 2011 - AWS US-East Zone EBS Outage
AWS Outage Report
Netflix Techblog Report
http://techblog.netflix.com/2011/04/lessons-netflix-learned-from-aws-outage.html
February 24th, 2010 - Google App Engine Power Outage
Google Forum Report
July 20th, 2008 - AWS Global S3 Gossip Protocol Corruption
AWS Outage Report
Friday, October 26, 2012
What's a Distinguished Engineer?
A recent post by John Allspaw on what it means to be a senior engineer reminded me of something I put together years ago while I was a Distinguished Engineer at Sun. One question from senior engineers looking at their career path was what did it take to become a Distinguished Engineer?
Although Sun is no more, across the industry, there are engineers who are "distinguished" and the title is used in a few places. At Sun, there were between 50 and 100 people in the role, who were mostly director level individual contributors, although there were also Sun Fellows who were VP level, and some were also line managers.
I boiled it down into a few questions.
First I made a list of the names of all the Sun Distinguished Engineers and Fellows, and the first question was "how many of these names do you recognize, and know what they did". The intent is to get a baseline level of understanding of what might be expected. The list included people who invented software languages and frameworks that lots of people use, microprocessor architects, and fundamental researchers in security and networking. There were also CTOs of companies that Sun had acquired, and a few like me who mostly got in through writing books that everyone else had read.
The next question is "how many of these people know who you are?". If you think you did do something special, we would expect that the existing Distinguished Engineers would have heard of it. Since at Sun the way to become a DE involved having the existing DE and Fellows vote for you, this was critical.
The final question was "how many DE and Fellows are hanging around your cube on a regular basis waiting to talk to you?". This shows that you are the go-to person for something that matters.
Translating this into a broader context, more current questions for being distinguished might be "Do the top conferences invite you to speak?", "How many of the other invited speakers and conference organizers do you know?" and "how many know you?". The other dimension of what you did to deserve it is nowadays a mixture of open source projects that lots of people use, or key ideas shared through books or blogs.
Here's the original slide from 2002, how many of these names do you know, what did they do then and where are they now?
Sunday, September 02, 2012
Solar Power Update - Annual Costs
I've blogged before about our solar power installation and we just completed our first full year where we didn't change anything, so we have a clear baseline of how much we generated and used, which I will describe in this post.
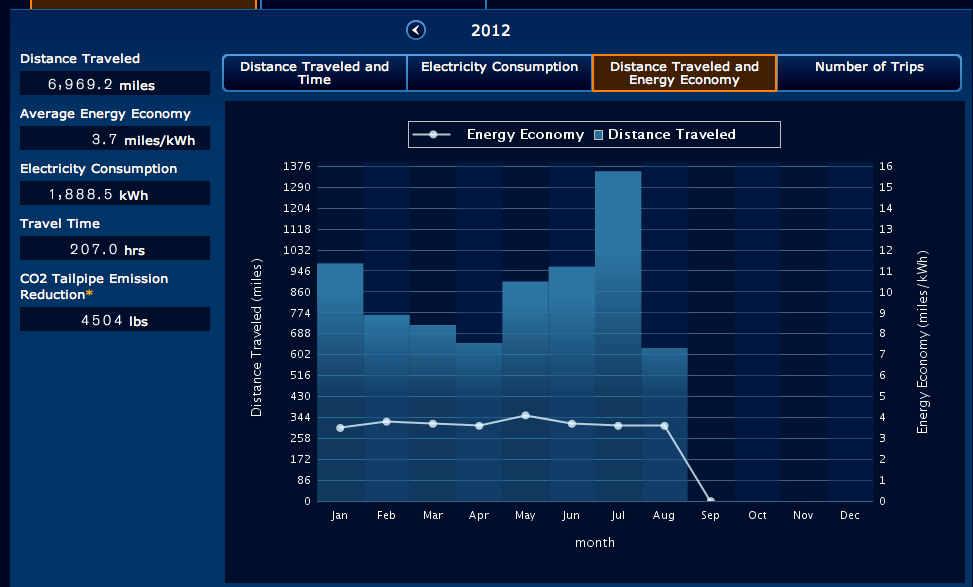
Our system is a grid tied net metering setup. This means that we generate more electricity than we use during the day and run the meter backwards in the summer, then use (cheaper) electricity at night and in the winter from the grid. Once a year our PG&E bill is netted out and we pay the difference. Last year our total electric bill was about $500 but during the year we changed everything by adding a second solar array, a Nissan Leaf electric car and a heat pump for heating and cooling. This year, with a consistent setup for the entire period, our bill was negative, so we didn't owe PG&E anything. However, this didn't mean that PG&E paid us the difference, because the payback rule is based on how many KWh you generate rather than how much you would have paid for it. In our case, although our net bill was -$495, we used 610 KWh more than we generated for the whole year. The details of our PG&E bill are shown at the end of this post.
In effect, we could have used another $495 worth of electricity for free. Going into next year, we will set the heat pump to work harder at lower temperatures before it switches over to propane, which will reduce our carbon footprint and save us some propane costs. For some of last winter we used propane when the outside temperature fell below 45F, and at some point we reduced that to 40F. Unfortunately the controller setting we have is in increments of 5F, and I'm doubtful that we can pump heat out of air at 35F, but it's worth a try. We already converted our other appliances from propane to electric, and other than the heat pump our major consumers are a large tank electric water heater, induction range, clothes dryer, hot tub and well pump.
We did around 11,000 miles in the Nissan Leaf in the last year, but estimate that about a third of our charging was at work, as Laurel's commute is far enough to be an easy one way run, but requires a charge to get home again up the hill (we live at 2400ft, and she works at sea level!). She can take the car pool lane with the "white sticker" that pure electric cars get, which saves a lot of time, but running at high speed on the freeway uses a lot more power than around town. When I get to use the Leaf my commute is much closer and I don't bother charging it at work. Our long term average consumption is 3.7 miles/KWh, which is worse than most Leaf owners because of the freeway miles, hill climbing and "having fun". We don't pay for charging at work, and the marginal cost of electricity at home is zero because we are generating a negative net bill for the year, so we only use the "ECO" driving style if we are pushing the limits of its range on an unusual trip. The Leaf is the first car we pick for drives in its range, it's entertaining to drive as well as having extremely low running costs. All it needs for maintenance is tires, there is no engine oil to change, and the brakes wear very slowly due to electric regeneration. Here's the year so far as recorded by the Leaf's "Carwings" system.
The PG&E tariff we are on is called E6 Net Energy Metering, it has three rates for the summer, and two rates in the winter. The rules and rates are described in these documents at the PG&E web site: Rules http://www.pge.com/tariffs/tm2/pdf/ELEC_SCHEDS_NEM.pdf and Rates http://www.pge.com/tariffs/tm2/pdf/ELEC_SCHEDS_E-6.pdf
The rate that PG&E will pay us for any extra KWh we generate is about 3 cents/KWh as described in this document http://www.pge.com/includes/docs/pdfs/shared/solar/AB920_RateTable.pdf
Our base overnight rate that we pay is around 10 cents/KWh, the afternoon rate is around 28 cents/KWh, this is why we can generate hundreds of dollars in a negative bill while using hundreds of KWh.
Our solar setup is in two arrays that I described on my blog before, the total summer peak output is about 10KW, and we get up to 70KWh per day. In the winter this drops to about 40KWh per day, and clouds and rainy days greatly reduce the output. We're in a sunny spot on top of the mountains, and the monthly output from the 6.5KW array is shown in the plots below since we turned it on in April 2011. The other array adds about half this amount. Our annual true-up period runs from the beginning of September to the end of August.
PG&E send us a bill every month for about $11 of connection fees and taxes, and the current running total. Our final bill for the last year is shown below. Solar costs were described in a previous post.
Saturday, June 16, 2012
Cloud Application Architectures: GOTO Aarhus, Denmark, October
Thanks to an invite via Michael Nygard, I ended up as a track chair for the GOTO Aarhus conference in Denmark in early October. The track subject is Cloud Application Architectures, and we have three speakers lined up. You can register with a discount using the code crof1000.
We are starting out with a talk from the Citrix Cloudstack folks about how to architect applications on open portable clouds. These implement a subset of functionality but have more implementation flexibility than public cloud services. [Randy Bias of Cloudscaling was going to give this talk but had to pull out of the trip due to other commitments].
To broaden our perspective somewhat, and get our hands dirty with real code, the next talk is a live demonstration by Ido Flatow, Building secured, scalable, low-latency web applications with the Windows Azure Platform.
There are many other excellent speakers at this event, which is run by the same team as the global series of QCon conferences, unfortunately, the cloud track runs at at the same time as Michael Nygard and Jez Humble on Continuous Delivery and Continuous Integration, however I'm doing another talk in the NoSQL track, (along with Martin Fowler and Coda Hale). Running Netflix on Cassandra in the Cloud.
I'm looking forward to meeting old friends, getting to know some new people, and visiting Denmark for the first time. See you there!
We are starting out with a talk from the Citrix Cloudstack folks about how to architect applications on open portable clouds. These implement a subset of functionality but have more implementation flexibility than public cloud services. [Randy Bias of Cloudscaling was going to give this talk but had to pull out of the trip due to other commitments].
To broaden our perspective somewhat, and get our hands dirty with real code, the next talk is a live demonstration by Ido Flatow, Building secured, scalable, low-latency web applications with the Windows Azure Platform.
In this session we will construct a secured, durable, scalable, low-latency web application with Windows Azure - Compute, Storage, CDN, ACS, Cache, SQL Azure, Full IIS, and more. This is a no-slides presentation!Finally I will be giving my latest update on Globally Distributed Cloud Applications at Netflix.
Netflix grew rapidly and moved its streaming video service to the AWS cloud between 2009 and 2010. In 2011 the architecture was extended to use Apache Cassandra as a backend, and the service was internationalized to support Latin America. Early in 2012 Netflix launched in the UK and Ireland, using the the combination of AWS capacity in Ireland and Cassandra to create a truly global backend service. Since then the code that manages and operates the global Netflix platform is being released as a series of open source projects at netflix.github.com (Asgard, Priam etc.). The platform is structured as a large scale PaaS, strongly leveraging advanced features of AWS to deploy many thousands of instances. The platform has primary language support for Java/Tomcat with most management tools built using Groovy/Grails and operations tooling in Python. Continuous integration and deployment tooling leverages Jenkins, Ivy/Gradle, Artifactory. This talk will explain how to build your own custom PaaS on AWS using these components.
There are many other excellent speakers at this event, which is run by the same team as the global series of QCon conferences, unfortunately, the cloud track runs at at the same time as Michael Nygard and Jez Humble on Continuous Delivery and Continuous Integration, however I'm doing another talk in the NoSQL track, (along with Martin Fowler and Coda Hale). Running Netflix on Cassandra in the Cloud.
Netflix used to be a traditional Datacenter based architecture using a few large Oracle database backends. Now it is one of the largest cloud based architectures, with master copies of all data living in Cassandra. This talk will discuss how we made the transition, how we automated and open sourced Cassandra management for tens of clusters and hundreds of nodes using Priam and Astyanax, backups, archiving and performance and scalability benchmarks.
I'm looking forward to meeting old friends, getting to know some new people, and visiting Denmark for the first time. See you there!
Sunday, April 29, 2012
It's not obvious how to be insanely simple
three books that I read recently resonated with me and fitted together so I'm going to try to make sense of them in a blog post rather than in a series of cryptic tweets.
My son (who is a product manager at eBay) told me about the most recent publication:
Insanely Simple: The Obsession That Drives Apple's Success by Ken Segall
At the Defrag conference last year I saw Duncan Watts present and recently finished reading his book Everything Is Obvious: Once You Know The Answer
I also recently watched Sam Harris give his talk on Free Will, and then read the book.
The connection starts with Free Will, which explains what is really going in our heads, along with Everything is Obvious which explains how our minds work collectively and interact with the real world these two books are the "Missing Manuals" for our brains. It's hard enough to figure out what is going on in the world and how best to navigate it, but it's doubly hard when you don't realize how your subconscious is pulling the strings and how common sense is confusing everyone around you.
Inside your head, the conscious thread of thoughts that you hear are post rationalizing decisions that your subconscious mind has already made. Feeding yourself a broad range of information with an open mind, connecting to your intuition and letting the power of your subconscious find the right patterns and responses lets you make faster and better decisions.
In society, we are surrounded by common sense explanations that we use to post rationalize the events around us and which are fed to us by the media, historians, politicians and our friends. Duncan deconstructs common sense to show that these explanations are mirages driven by our inner need to find a narrative and cause for effects that are essentially random co-incidences with far less significance than we assume. He then explains what un-common sense looks like and how to question the received wisdom and have better strategies for getting things done successfully.
I'm not going to summarize the whole book but there is a very useful section that should be read by anyone doing "big data analytics" that sets out the kind of things that are know-able and what (and why) other things will always remain un-knowable and impossible to predict. The advice I distilled from the discussion of strategy is that there is so much randomness in the outcome of business decisions that you cannot reliably evaluate the difference between a good strategy and a poor strategy. If you are able to get ever more detailed data about what happened you become more convinced in the value of your analysis, but the predictions you make about what to do next don't get any better. This is a counter-intuitive outcome (i.e. it violates common sense), so please read the book, which explains why you shouldn't be trusting your common sense in the first place.
The positive things we can do to overcome random outcomes really resonated with me, as they put into words several of the things I've been doing for many years, which have in some sense given me a better way to understand what's going on and get stuff done. They also describe many of the ways that Netflix figures out how to build it's products.
The first thing I do when I hear something like A caused B is a reflex reaction, I flip it around in my head, take the devils advocate position, look at the situation from a few different angles. This can be quite annoying in "polite company" as I tend to question received wisdom and common sense assertions, however I usually find a missing piece of information that could falsify the assertion, and ask the question. It could be as simple as asking exactly what time A and B happened, since if B turned out to happen before A then the assertion is clearly false. In statistics and physics this is codified as asserting the null hypothesis. (I'm the son of a statistician and I have a Physics degree...).
At Netflix we always try to construct parallel "A/B" tests of our hypotheses, like the double blind tests used in clinical trials of new medicines. We take a large number of new customers and give them a range of different experiences for long enough to measure a difference in their responses. This is the only way to reliably tell whether a new feature works, and it often goes against the common sense of what we expect and what many customers and industry analysts helpfully suggest we should be doing. As Duncan explains we can usually figure out what factors will affect an outcome, but we are extremely poor judges of how to weight those factors, even with post rationalization of what we saw happen, and all we can do is bias the statistics in a preferred direction. A recurring example is the suggestion that Netflix should allow half-stars in its movie ratings, but it turns out that given more fine grain choice fewer people rate movies, and the reduction in the number of data points out-weighs the increased accuracy. We can post rationalize why this occurs as an example of giving people too much choice, but we don't have to rationalize it, we just measured it.
In the discussion of strategy Duncan talks about creating a set of strategies that cover many scenarios, and using scenario planning to build more flexible and fuzzy strategies which are more likely to work under a range of random external influences. By putting yourself in the path of possible good randomness and avoiding bad outcomes, you can "make your own luck". By detecting problems early and having the flexibility to adapt your strategy you can run around the problems that will randomly come your way. If instead you concentrate on coming up with the best possible strategy or assuming that previous success was due to strategy rather than random outcomes you are building a brittle future that is likely to disappoint you.
The final point I will lift from Duncan's discussion of uncommon sense is that speed of execution and iteration is another fine way to cheat the chance events that will derail your plans. Long term detailed plans are a waste of time. This is one of the foundations of agile development, where rapid iteration of product features lets you discover what your users actually do with your product, as opposed to what you thought they would do or what they say they will do.
This leads to the Insanely Simple book, which talks about Apple's approach to product design, with particular emphasis on branding and marketing since Ken Segall was the guy who came up with the i in iMac and has many other fascinating stories. One reason I like working at Netflix is that for agile web services, product ideas can be built and tested in a week or a month, and fixed in minutes. For Apple they work on products for years and need to have them work perfectly when they are released. This gives them two big problems, since its hard to iterate and hard to test ideas and products in advance. Their solution seems to be that they allow better ideas to form and develop, take bigger risks and make decisions faster than their competition, which helps stay ahead of the market. The Insanely Simple design philosophy is based on the idea that its easy to listen to all those great common sense ideas about features your product has to have, but if you learn to ignore the common sense and give the customers a simple and distilled experience you will reach beyond the people who want a complicated product and find a much bigger market of people who were waiting for a simple way to get something done. Apple's competitors are so bogged down in committees and approval processes, and helpful common sense advice from customers that they are unable to release simple products.
A key example from the book is that Apple has had many award winning advertising campaigns, "Think Different", "PC and Mac" and the iPod silhouette, and none of them were test marketed in advance. Their competitors make less risky adverts after getting broad internal consensus, take much longer to get them to market and fail to understand that the success of an advert is a randomized event (with lots of useless common sense post rationalizations) so the test market response is a very poor predictor of success. It's more important to be bold, different and go big. For example Apple only advertised Think Different on the back cover of magazines, which costs far more but has a much bigger impact than inside pages.
From these three books I've found some useful focus on how to approach things, but they also give me some backup to explain to others why I think some things are important. A key part of what I have been doing for Netflix is looking out into the future of cloud and related technologies and developing a portfolio of fuzzy strategies and options. They don't all work out, but by having a well instrumented but loosely coordinated architecture that doesn't have central control and strict processes we can iterate rapidly, adopt (and discard) interesting new technologies as they come along. We can all have more fun and less frustration making Netflix Insanely Simple, and ignore all the bad common sense advice and analyst opinions that swirl around everything we do.
I'm planning a complete re-write of my cloud architecture tutorial for Gluecon in May, that will be a great opportunity to discuss these things in person over a few beers, and now is a good time to sign up to attend - you can get a 10% discount with code spkr12.
Monday, March 19, 2012
Ops, DevOps and PaaS (NoOps) at Netflix
There has been a sometimes heated discussion on twitter about the term NoOps recently, and I've been quoted extensively as saying that NoOps is the way developers work at Netflix. However, there are teams at Netflix that do traditional Operations, and teams that do DevOps as well. To try and clarify things I need to explain the history and current practices at Netflix in chunks of more than 140 characters at a time.
When I joined Netflix about five years ago, I managed a development team, building parts of the web site. We also had an operations team who ran the systems in the single datacenter that we deployed our code to. The systems were high end IBM P-series virtualized machines with storage on a virtualized Storage Area Network. The idea was that this was reliable hardware with great operational flexibility so that developers could assume low failure rates and concentrate on building features. In reality we had the usual complaints about how long it took to get new capacity, the lack of consistency across supposedly identical systems, and failures in Oracle, in the SAN and the networks, that took the site down too often for too long.
At that time we had just launched the streaming service, and it was still an experiment, with little content and no TV device support. As we grew streaming over the next few years, we saw that we needed higher availability and more capacity, so we added a second datacenter. This project took far longer than initial estimates, and it was clear that deploying capacity at the scale and rates we were going to need as streaming took off was a skill set that we didn't have in-house. We tried bringing in new ops managers, and new engineers, but they were always overwhelmed by the fire fighting needed to keep the current systems running.
Netflix is a developer oriented culture, from the top down. I sometimes have to remind people that our CEO Reed Hastings was the founder and initial developer of Purify, which anyone developing serious C++ code in the 1990's would have used to find memory leaks and optimize their code. Pure Software merged with Atria and Rational before being swallowed up by IBM. Reed left IBM and formed Netflix. Reed hired a team of very strong software engineers who are now the VPs who run developer engineering for our products. When we were deciding what to do next Reed was directly involved in deciding that we should move to cloud, and even pushing us to build an aggressively cloud optimized architecture based on NoSQL. Part of that decision was to outsource the problems of running large scale infrastructure and building new datacenters to AWS. AWS has far more resources to commit to getting cloud to work and scale, and to building huge datacenters. We could leverage this rather than try to duplicate it at a far smaller scale, with greater certainty of success. So the budget and responsibility for managing AWS and figuring out cloud was given directly to the developer organization, and the ITops organization was left to run its datacenters. In addition, the goal was to keep datacenter capacity flat, while growing the business rapidly by leveraging additional capacity on AWS.
Over the next three years, most of the ITops staff have left and been replaced by a smaller team. Netflix has never had a CIO, but we now have an excellent VP of ITops Mike Kail (@mdkail), who now runs the datacenters. These still support the DVD shipping functions of Netflix USA, and he also runs corporate IT, which is increasingly moving to SaaS applications like Workday. Mike runs a fairly conventional ops team and is usually hiring, so there are sysadmin, database,, storage and network admin positions. The datacenter footprint hasn't increased since 2009, although there have been technology updates, and the over-all size is order-of-magnitude a thousand systems.
As the developer organization started to figure out cloud technologies and build a platform to support running Netflix on AWS, we transferred a few ITops staff into a developer team that formed the core of our DevOps function. They build the Linux based base AMI (Amazon Machine Image) and after a long discussion we decided to leverage developer oriented tools such as Perforce for version control, Ivy for dependencies, Jenkins to automate the build process, Artifactory as the binary repository and to construct a "bakery" that produces complete AMIs that contain all the code for a service. Along with AWS Autoscale Groups this ensured that every instance of a service would be totally identical. Notice that we didn't use the typical DevOps tools Puppet or Chef to create builds at runtime. This is largely because the people making decisions are development managers, who have been burned repeatedly by configuration bugs in systems that were supposed to be identical.
By 2012 the cloud capacity has grown to be order-of-magnitude 10,000 instances, ten times the capacity of the datacenter, running in nine AWS Availability zones (effectively separate datacenters) on the US East and West coast, and in Europe. A handful of DevOps engineers working for Carl Quinn (@cquinn - well known from the Java Posse podcast) are coding and running the build tools and bakery, and updating the base AMI from time to time. Several hundred development engineers use these tools to build code, run it in a test account in AWS, then deploy it to production themselves. They never have to have a meeting with ITops, or file a ticket asking someone from ITops to make a change to a production system, or request extra capacity in advance. They use a web based portal to deploy hundreds of new instances running their new code alongside the old code, put one "canary" instance into traffic, if it looks good the developer flips all the traffic to the new code. If there are any problems they flip the traffic back to the previous version (in seconds) and if it's all running fine, some time later the old instances are automatically removed. This is part of what we call NoOps. The developers used to spend hours a week in meetings with Ops discussing what they needed, figuring out capacity forecasts and writing tickets to request changes for the datacenter. Now they spend seconds doing it themselves in the cloud. Code pushes to the datacenter are rigidly scheduled every two weeks, with emergency pushes in between to fix bugs. Pushes to the cloud are as frequent as each team of developers needs them to be, incremental agile updates several times a week is common, and some teams are working towards several updates a day. Other teams and more mature services update every few weeks or months. There is no central control, the teams are responsible for figuring out their own dependencies and managing AWS security groups that restrict who can talk to who.
Automated deployment is part of the normal process of running in the cloud. The other big issue is what happens if something breaks. Netflix ITops always ran a Network Operations Center (NOC) which was staffed 24x7 with system administrators. They were familiar with the datacenter systems, but had no experience with cloud. If there was a problem, they would start and run a conference call, and get the right people on the call to diagnose and fix the issue. As the Netflix web site and streaming functionality moved to the cloud it became clear that we needed a cloud operations reliability engineering (CORE) team, and that it would be part of the development organization. The CORE team was lucky enough to get Jeremy Edberg (@jedberg - well know from running Reddit) as its initial lead engineer, and also picked up some of the 24x7 shift sysadmins from the original NOC. The CORE team is still staffing up, looking for Site Reliability Engineer skill set, and is the second group of DevOps engineers within Netflix. There is a strong emphasis on building tools too make as much of their processes go away as possible, for example they have no run-books, they develop code instead,
To get themselves out of the loop, the CORE team has built an alert processing gateway. It collects alerts from several different systems, does filtering, has quenching and routing controls (that developers can configure), and automatically routes alerts either to the PagerDuty system (a SaaS application service that manages on call calendars, escalation and alert life cycles) or to a developer team email address. Every developer is responsible for running what they wrote, and the team members take turns to be on call in the PagerDuty rota. Some teams never seem to get calls, and others are more often on the critical path. During a major production outage con call, the CORE team never make changes to production applications, they always call a developer to make the change. The alerts mostly refer to business transaction flows (rather than typical operations oriented Linux level issues) and contain deep links to dashboards and developer oriented Application Performance Management tools like AppDynamics which let developers quickly see where the problem is at the Java method level and what to fix,
The transition from datacenter to cloud also invoked a transition from Oracle, initially to SimpleDB (which AWS runs) and now to Apache Cassandra, which has its own dedicated team. We moved a few Oracle DBAs over from the ITops team and they have become experts in helping developers figure out how to translate their previous experience in relational schemas into Cassandra key spaces and column families. We have a few key development engineers who are working on the Cassandra code itself (an open source Java distributed systems toolkit), adding features that we need, tuning performance and testing new versions. We have three key open source projects from this team available on github.com/Netflix. Astyanax is a client library for Java applications to talk to Cassandra, CassJmeter is a Jmeter plugin for automated benchmarking and regression testing of Cassandra, and Priam provides automated operation of Cassandra including creating, growing and shrinking Cassandra clusters, and performing full and incremental backups and restores. Priam is also written in Java. Finally we have three DevOps engineers maintaining about 55 Cassandra clusters (including many that span the US and Europe), a total of 600 or so instances. They have developed automation for rolling upgrades to new versions, and sequencing compaction and repair operations. We are still developing our Cassandra tools and skill sets, and are looking for a manager to lead this critical technology, as well as additional engineers. Individual Cassandra clusters are automatically created by Priam, and it's trivial for a developer to create their own cluster of any size without assistance (NoOps again). We have found that the first attempts to produce schemas for Cassandra use cases tend to cause problems for engineers who are new to the technology, but with some familiarity and assistance from the Cloud Database Engineering team, we are starting to develop better common patterns to work to, and are extending the Astyanax client to avoid common problems.
In summary, Netflix stil does Ops to run its datacenter DVD business. we have a small number of DevOps engineers embedded in the development organization who are building and extending automation for our PaaS, and we have hundreds of developers using NoOps to get their code and datastores deployed in our PaaS and to get notified directly when something goes wrong. We have built tooling that removes many of the operations tasks completely from the developer, and which makes the remaining tasks quick and self service. There is no ops organization involved in running our cloud, no need for the developers to interact with ops people to get things done, and less time spent actually doing ops tasks than developers would spend explaining what needed to be done to someone else. I think that's different to the way most DevOps places run, but its similar to other PaaS enviroments, so it needs it's own name, NoOps. [Update: the DevOps community argues that although it's different, it's really just a more advanced end state for DevOps, so lets just call it PaaS for now, and work on a better definition of DevOps].
Friday, March 16, 2012
Cloud Architecture Tutorial
I presented a whole day tutorial at QCon London on March 5th, and presented subsets at an AWS Meetup, a Big Data / Cassandra Meetup and a Java Meetup the same week. I updated the slides and split them into three sections which are hosted on http://slideshare.net/adrianco along with all my other presentations. You can find many more related slide decks at http://slideshare.net/Netflix and other information at the Netflix Tech Blog.
The first section tells the story of why Netflix migrated to cloud, how we think about choosing AWS as our cloud supplier and what features of the Netflix site were moved to the cloud over the last three years.
The second section is a detailed explanation of the globally distributed Java based Platform as a Service (PaaS) we built, the open source components that we depend on, and the open source projects that we have started to share at http://netflix.github.com.
The final section talks about how we run these PaaS services in the cloud, and includes details of our million writes per second scalability benchmark.
If you would like to see these slides presented in person, I'm teaching a half day cloud architecture tutorial at Gluecon in Broomfield Colorado in May 23-24th. I hope to see you there...
The first section tells the story of why Netflix migrated to cloud, how we think about choosing AWS as our cloud supplier and what features of the Netflix site were moved to the cloud over the last three years.
Cloud Architecture Tutorial - Why and What (1of 3)
View more presentations from Adrian Cockcroft
The second section is a detailed explanation of the globally distributed Java based Platform as a Service (PaaS) we built, the open source components that we depend on, and the open source projects that we have started to share at http://netflix.github.com.
Cloud Architecture Tutorial - Platform Component Architecture (2of3)
View more presentations from Adrian Cockcroft
The final section talks about how we run these PaaS services in the cloud, and includes details of our million writes per second scalability benchmark.
Cloud Architecture Tutorial - Running in the Cloud (3of3)
View more presentations from Adrian Cockcroft
If you would like to see these slides presented in person, I'm teaching a half day cloud architecture tutorial at Gluecon in Broomfield Colorado in May 23-24th. I hope to see you there...
Thursday, January 19, 2012
Thoughts on SimpleDB, DynamoDB and Cassandra
I've been getting a lot of questions about DynamoDB, and these are my personal thoughts on the product, and how it fits into cloud architectures.
I'm excited to see the release of DynamoDB, it's a very impressive product with great performance characteristics. It should be the first option for startups and new cloud projects on AWS. I also think it marks the turning point on solid state disks, they will be the default for new database products and benchmarks going forward.
There are a few use cases where SimpleDB may still be useful, but DynamoDB replaces it in almost all cases. I've talked about the history of Netflix use of SimpleDB before, but it's relevant to the discussion on DynamoDB, so here goes.
When Netflix was looking at moving to cloud about three years ago we had an internal debate about how to handle storage on AWS. There were strong proponents for using MySQL, SimpleDB was fairly new, and other alternatives were nascent NoSQL projects or expensive enterprise software. We started some pathfinder projects to explore the two alternatives and decided to port an existing MySQL app to AWS, while building a replication pipeline that copied data out of our Oracle datacenter systems into SimpleDB to be consumed in the cloud. The MySQL experience showed that we would have trouble scaling, and SimpleDB seemed reliable, so we went ahead and kept building more data sources on SimpleDB, with large blobs of data on S3.
Along the way we put memcached in front of SimpleDB and S3 to improve read latency. The durability of SimpleDB is its strongest point, we have had Oracle and SAN data corruption bugs in the Datacenter over the last few years, but never lost or corrupted any SimpleDB data. The limitations of SimpleDB are its biggest problem. We worked around limits on table size, row and attribute size, and per-request overhead caused by http requests needing to be authenticated for every call.
So the lesson here is that for a first step into NoSQL, we went with a hosted solution so that we didn't have to build a team of experts to run it, and we didn't have to decide in advance how much scale we needed. Starting again from scratch today, I would probably go with DynamoDB. It's a low "friction" and developer friendly solution.
Late in 2010 we were planning the next step, turning off Oracle and making the cloud the master copy of the data. One big problem is that our backups and archives were based on Oracle, and there was no way to take a snapshot or incremental backup of SimpleDB. The only way to get data out in bulk is to run "SELECT * FROM table" over HTTP and page the requests. This adds load, takes too long, and costs a lot because SimpleDB charges for the time taken in SELECT calls.
We looked at about twenty NoSQL options during 2010, trying to understand what the differences were, and eventually settled on Cassandra as our candidate for prototyping. In a week or so, we had ported a major data source from SimpleDB to Cassandra and were getting used to the new architecture, running benchmarks etc. We evaluated some other options, but decided to take Cassandra to the next stage and develop a production data source using it.
The things we liked about Cassandra were that it is written in Java (we have a building full of Java engineers), it is packed full of state of the art distributed systems algorithms, we liked the code quality, we could get commercial support from Datastax, it is scalable and as an extra bonus it had multi-region support. What we didn't like so much was that we had to staff a team to own running Cassandra for us, but we retrained some DBAs and hired some good engineers including Vijay Parthasarathy, who had worked on the multi-region Cassandra development at Cisco Webex and who recently became a core committer on the Apache Cassandra project. We also struggled with the Hector client library, and have written our own (which we plan to release soon). The blessing and a curse of Cassandra is that it is an amazingly fast moving project. New versions come fast and furiously, which makes it hard to pick a version to stabilize on, however the changes we make turn up in the mainstream releases after a few weeks. Saying "Cassandra doesn't do X" is more of a challenge than a statement. If we need "X" we work with the rest of the Apache project to add it.
Throughout 2010 the product teams at Netflix gradually moved their backend data sources to Cassandra, we worked out the automation we needed to do easy self service deployments and ended up with a large number of clusters. In preparation for the UK launch we also made changes to Cassandra to better support multi-region deployment on EC2, and we are currently running several Cassandra clusters that span the US and European AWS regions.
Now that DynamoDB has been released, the obvious question is whether Netflix has any plans to use it. The short answer is no, because it's a subset of the Cassandra functionality that we depend on. However that doesn't detract from the major step forward from SimpleDB in performance, scalability and latency. For new customers, or people who have outgrown the scalability of MySQL or MongoDB, DynamoDB is an excellent starting point for data sources on AWS. The advantages of zero administration combined with the performance and scalability of a solid state disk backend are compelling.
Personally my main disappointment with DynamoDB is that it doesn't have any snapshot or incremental backup capability. The AWS answer is that you can extract data into EMR then store it in S3. This is basically the same answer as SimpleDB, it's a full table scan data extraction (which takes too long and costs too much and isn't incremental). The mechanism we built for Cassandra leverages the way that Cassandra writes immutable files to get a callback and compress/copy them to S3 as they are written, it's extremely low overhead. If we corrupt our data with a code bug and need to roll back, or take a backup in production and restore in test, we have all the files archived in S3.
One argument against DynamoDB is that DynamoDB is on AWS only, so customers could get locked in, however it's easy to upgrade applications from SimpleDB, to DynamoDB and to Cassandra. They have similar schema models, consistency options and availability models. It's harder to go backwards, because Cassandra has more features and fewer restrictions. Porting between NoSQL data stores is trivial compared to porting between relational databases, due to the complexity of the SQL language dialects and features and the simplicity of the NoSQL offerings. Starting out on DynamoDB then switching to Cassandra when you need more direct control over the installation or Cassandra specific features like multi-region support is a very viable strategy.
As early adopters we have had to do a lot more pioneering engineering work than more recent cloud converts. Along the way we have leveraged AWS heavily to accelerate our own development, and built a lot of automation around Cassandra. While SimpleDB has been a minor player in the NoSQL world DynamoDB is going to have a much bigger impact. Cassandra has matured and got easier to use and deploy over the last year but it doesn't scale down as far. By that I mean a single developer in a startup can start coding against DynamoDB without needing any support and with low and incremental costs. The smallest Cassandra cluster we run is six m1.xlarge instances spread over three zones with triple replication.
I've been saying for a while that 2012 is the year that NoSQL goes mainstream, DynamoDB is another major step in validating that move. The canonical CEO to CIO conversation is moving from 2010: "what's our cloud strategy?", 2011: "what's our big data strategy?" to 2012: "what's our NoSQL strategy?".
Friday, December 30, 2011
How Netflix gets out of the way of innovation
#defrag 2011 presentation script.
I'm the cloud architect for Netflix, but rather than tell you about why we moved Netflix to a cloud architecture or how we built our cloud architecture, I'm going to tell you what we do differently at Netflix to create a culture that supports innovation.
What is it that lets us get things done very quickly. Sometimes a bit too qwikly…. but how did we keep making big strategic moves, from DVD to streaming, from Datacenter to Public Cloud, from USA only to International, all in very short timescales with a fairly small team of engineers.
My presentation slides are just box-shots of movies and TV shows that are available on Netflix streaming. This script is based on the notes I made to figure out what I was going to say for each box shot. If some of you see a show you didn't know we had and want to watch that would make me happy, you can click on the box shot to visit that movie at Netflix, they were all available for streaming in the USA at the time of writing.

I've attempted to match the box shots loosely as cues to what I'm saying, but I've also used a musical theme in places since this is for Defrag and Defrag rocks!

Netflix is now one of the largest sites that runs almost entirely on public cloud infrastructure. We have become a poster child for how to build an architecture that takes full advantage of the Amazon Web Services cloud. But when I talk to other large companies about what we have done, they seem to have a lot of reasons why they couldn't or didn't do what we did, even if they wanted to.

Why is that? Why are we heading in one direction while everyone else is going the other way? Are we crazy or are they zombies? Well, I've worked at other large companies so I have some perspective on the issues.

Before I joined Netflix I worked at eBay for a few years, and helped found eBay Research Labs. This was setup because eBay felt it wasn't innovating fast enough, and they were looking for the one missing ingredient that would drive more innovation into the company.

This is a fairly common approach. "You guys go and be innovative, then hopefully we will find ways to spread it around a bit." Unfortunately the end result of setting up a separate group to add innovation to a big company is more comical than useful.

The most interesting projects got tied in knots, they trod on too many toes or were scary. We visited Xerox Parc and IBM Santa Teresa Labs to discuss how they were setup, to try and learn what might work., and we went to an Innovation Forum in New York. That was weird, some of the primary examples they were talking about emulating were eBay and Paypal!

The projects that did get out were minor tweaks to existing ideas, they could be fun, but ultimately not very interesting.

So I had to break out of there and find something new to do, and in 2007 I joined Netflix just as they first launched streaming.

One of the key attractions for me was the Netflix culture I heard about in the interviews, I wanted to get inside their heads and figure out if what they were describing was real, and if so, was it sustainable as the company grew.

What I found out over the next few years is that the culture is what enables innovation, so that Netflix can get things done quickly that other companies are too scared or too slow to try. The rest of this talk is about the key things that we do differently at Netflix.

Before I get into them I want to warn you that even with a roadmap and a guide, you probably won't be able to follow this path if you are in a large established company. Your existing culture won't let you. However if you are creating a new company from scratch, I hope you can join me in what I hope is the future of cool places to work.

Here's the key insight. It's the things you don't do that make the difference. You don't add innovation to a company culture, you get out of its way.
I'm mostly going for SciFi at this point, because it's going to sound like I was beamed in from the future to some of you.

Let me repeat that. You have to setup a company that doesn't do many of the things you would consider business as usual. That's why it's so hard to retrofit.

How about some audience participation? Hands up everyone who hates answering questions by putting their hands up..

Who works at a company that has more than one product line? Do you get along? The problem is that the company loses focus and has trouble allocating resources where they are needed so there are big fights. Pick one big thing and do it well. For Netflix, our addressable market is everyone in the universe who likes watching movies and TV shows, that should keep us busy for a while.

Who has teams spread over multiple sites and countries? We don't. It adds communication and synchronization overhead that slows your organization down. For the geeks, think of Amdahl's law applied to people. We have as many people as possible in the same building on the same site. We are planning a new bigger building to make sure we can keep everyone close together. High bandwidth, low latency communication.

Who's worked for a place that bought another company, then run it into the ground, laid everyone off and wrote down the value. Over and over again. It's crazy. I don't think Netflix has ever bought another company. It's a huge disruption to the culture, if you see something you like just hire away their best people and out execute them in the market.

Who has junior engineers, graduate hires and interns writing code? We don't. We find that engineers who cost twice as much are far more than twice as productive, and need much less management overhead. Reducing management overhead is a key enabler for an innovative culture. Engineers who don't need to be managed are worth paying extra for. We are tiny compared to companies like Google, they take on raw talent and develop it, we sometimes take a chance on someone with only five years experience.

Who has an architecture review board and centralized coding standards? We don't have that either. What we do have is tooling that creates a path of least resistance, which combined with peer pressure keeps quality high. The engineers are free and responsible for figuring it out for themselves.

Who has an ITops team that owns keeping code running in production? We don't. The developers run what they wrote. Everyone's cell phone is in the pagerduty rota, the trick is making sure you don't need to get called. All the ops people here have horror stories of stupid developers, and vice versa, but it doesn't have to be that way. We have one dev organization that does everything and no IT ops org involvement in our AWS cloud deployment.

Who has to ask permission before deploying 100's or 1000's of servers? We don't. The developers use our portal directly, they have to file a Change Management ticket to record what they did if it's in production, that's all. We've trained our developers to operate their own code. We create and destroy up to 1000 servers a day, just pushing new code. AWS takes about 5 minutes to allocate 100 servers, it takes longer than that just to boot Linux on them.

Who has a centralized push cycle and has to wait for the next "train" before they can ship their code? We don't. Every team manages their own release schedule. New code updates frequently, and the pace slows for mature services. Teams are responsible for managing interface evolution and dependencies themselves. Freedom and responsibility again.

Who has project managers tracking deliverables? We don't. The line managers do it themselves. They own the resources and set the context for their teams. They have time to do this because we took the BS out of their role.
Managers have to be great at hiring, technical and hands on enough to architect what their team does, and project manage to deliver results. Don't split this into three people. Reduce management overhead, minimize BS and time wasted. Teams are typically 3-7 people. Have a weekly team meeting and 1on1 with each engineer to maintain context.

Who has a single standard for development tools? We don't. We assume developers already know how to make themselves productive. We provide some common patterns to get new hires started, like Eclipse, IntelliJ, on Mac, Windows. Some people use Emacs on Linux. Hire experienced engineers who care, and they will take care of code quality and standards without being told how to.

Who has to work with people they don't respect? It's much too disruptive. The only way to get high talent density is to get rid of the people who are out of their depth or coasting.

That also applies to what you might call brilliant jerks. Even if they do great work, the culture can't tolerate prima donna anti-social behavior, so people who don't trust others or share what they know don't fit in.

So does that mean we value conformity? No but it's really important to be comfortable as part of a high performance team, so we look for people who naturally over-communicate and have a secure confident personality type.

If you haven't experienced a high performance culture, think about what it's like to drive flat out at a race track. Some people will be too scared to deal with it and drive around white knuckled at 40 mph, some will be overconfident and crash on the first corner, but for people who fit into the high performance culture it's exhilarating to push yourself to go faster each lap, and learn from your peers without a speed limit. When you take out the BS and friction, everyone gets so much more done that productivity, innovation and rapid agile development just happen. This is the key message, removing obstacles to a high performance culture is how innovation happens throughout an organization. Doing less to get more.

We don't pay bonuses. We don't have grades other than senior engineer, manager, director, VP. We don't count the hours or the vacation days, we say "take some". Once a year we revise everyones salary to their peers and current market rate - based on what we are paying now to hire the best people we can find.

We also have what sounds like a crazy stock option plan that grants options every month, vests the same day, and they last 10 years even if you leave Netflix. The net of this is less work for managers, they can concentrate on hiring top people, and almost everyone that leaves takes a pay cut. The test we make is "would you fight to keep your engineers if they tried to leave". If not, let them go now and get someone better. We don't make it hard to let people go.

Some of you may be thinking this sounds expensive, but what is the value of being incredibly productive and able to move faster than your competition? You can get out ahead and establish a leading position before anyone else realizes you are even in the game. Remember how a few years ago the "Analysts" said that Netflix the DVD company was going to get killed by other companies streaming, then all of a sudden people realized that we were streaming more bandwidth than anyone else?

So what could possibly go wrong? We had a near miss recently, we went too fast, partly because we could, got unlucky and screwed up. The good thing is that Netflix could re-plan and execute on the fixes we need very quickly as well, with no internal angst and finger-pointing. Also there was an Asteroid nearby earlier this week. By the way, my stepdaughter @raedioactive was the art director for this movie.

So, you are at a crossroads, you could be on stage with Eric Clapton, or in the audience watching and wondering why you can't do what they are doing. It's a radically different way to construct a corporate culture, it doesn't work for everyone, and we can't all be up on stage with Eric, but the talent is out there if you start by building a culture focused on talent density to find it and keep it.

Is it going to be the goats or the glory? I just told you all to stop doing things, what could be easier than that? It takes less process, fewer rules and simpler principles. Give people freedom, hold them responsible, replace the ones that can't or won't perform in that environment. Focus on talent density and conserving management attention span by removing the BS from their jobs.

This is your challenge, can you get a band together and go on a mission to save your company? Stop doing all the things that are slowing you down, and get rid of the unproductive BS that clogs up your management and engineers.

I will take questions in the comments or on twitter to @adrianco. Thank you.

Each question got a new box shot, but all the answers were musical.
I'm the cloud architect for Netflix, but rather than tell you about why we moved Netflix to a cloud architecture or how we built our cloud architecture, I'm going to tell you what we do differently at Netflix to create a culture that supports innovation.
What is it that lets us get things done very quickly. Sometimes a bit too qwikly…. but how did we keep making big strategic moves, from DVD to streaming, from Datacenter to Public Cloud, from USA only to International, all in very short timescales with a fairly small team of engineers.
My presentation slides are just box-shots of movies and TV shows that are available on Netflix streaming. This script is based on the notes I made to figure out what I was going to say for each box shot. If some of you see a show you didn't know we had and want to watch that would make me happy, you can click on the box shot to visit that movie at Netflix, they were all available for streaming in the USA at the time of writing.
I've attempted to match the box shots loosely as cues to what I'm saying, but I've also used a musical theme in places since this is for Defrag and Defrag rocks!
Netflix is now one of the largest sites that runs almost entirely on public cloud infrastructure. We have become a poster child for how to build an architecture that takes full advantage of the Amazon Web Services cloud. But when I talk to other large companies about what we have done, they seem to have a lot of reasons why they couldn't or didn't do what we did, even if they wanted to.
Why is that? Why are we heading in one direction while everyone else is going the other way? Are we crazy or are they zombies? Well, I've worked at other large companies so I have some perspective on the issues.
Before I joined Netflix I worked at eBay for a few years, and helped found eBay Research Labs. This was setup because eBay felt it wasn't innovating fast enough, and they were looking for the one missing ingredient that would drive more innovation into the company.
This is a fairly common approach. "You guys go and be innovative, then hopefully we will find ways to spread it around a bit." Unfortunately the end result of setting up a separate group to add innovation to a big company is more comical than useful.
The most interesting projects got tied in knots, they trod on too many toes or were scary. We visited Xerox Parc and IBM Santa Teresa Labs to discuss how they were setup, to try and learn what might work., and we went to an Innovation Forum in New York. That was weird, some of the primary examples they were talking about emulating were eBay and Paypal!
The projects that did get out were minor tweaks to existing ideas, they could be fun, but ultimately not very interesting.
So I had to break out of there and find something new to do, and in 2007 I joined Netflix just as they first launched streaming.
One of the key attractions for me was the Netflix culture I heard about in the interviews, I wanted to get inside their heads and figure out if what they were describing was real, and if so, was it sustainable as the company grew.
What I found out over the next few years is that the culture is what enables innovation, so that Netflix can get things done quickly that other companies are too scared or too slow to try. The rest of this talk is about the key things that we do differently at Netflix.
Before I get into them I want to warn you that even with a roadmap and a guide, you probably won't be able to follow this path if you are in a large established company. Your existing culture won't let you. However if you are creating a new company from scratch, I hope you can join me in what I hope is the future of cool places to work.
Here's the key insight. It's the things you don't do that make the difference. You don't add innovation to a company culture, you get out of its way.
I'm mostly going for SciFi at this point, because it's going to sound like I was beamed in from the future to some of you.
Let me repeat that. You have to setup a company that doesn't do many of the things you would consider business as usual. That's why it's so hard to retrofit.
How about some audience participation? Hands up everyone who hates answering questions by putting their hands up..
Who works at a company that has more than one product line? Do you get along? The problem is that the company loses focus and has trouble allocating resources where they are needed so there are big fights. Pick one big thing and do it well. For Netflix, our addressable market is everyone in the universe who likes watching movies and TV shows, that should keep us busy for a while.
Who has teams spread over multiple sites and countries? We don't. It adds communication and synchronization overhead that slows your organization down. For the geeks, think of Amdahl's law applied to people. We have as many people as possible in the same building on the same site. We are planning a new bigger building to make sure we can keep everyone close together. High bandwidth, low latency communication.
Who's worked for a place that bought another company, then run it into the ground, laid everyone off and wrote down the value. Over and over again. It's crazy. I don't think Netflix has ever bought another company. It's a huge disruption to the culture, if you see something you like just hire away their best people and out execute them in the market.
Who has junior engineers, graduate hires and interns writing code? We don't. We find that engineers who cost twice as much are far more than twice as productive, and need much less management overhead. Reducing management overhead is a key enabler for an innovative culture. Engineers who don't need to be managed are worth paying extra for. We are tiny compared to companies like Google, they take on raw talent and develop it, we sometimes take a chance on someone with only five years experience.
Who has an architecture review board and centralized coding standards? We don't have that either. What we do have is tooling that creates a path of least resistance, which combined with peer pressure keeps quality high. The engineers are free and responsible for figuring it out for themselves.
Who has an ITops team that owns keeping code running in production? We don't. The developers run what they wrote. Everyone's cell phone is in the pagerduty rota, the trick is making sure you don't need to get called. All the ops people here have horror stories of stupid developers, and vice versa, but it doesn't have to be that way. We have one dev organization that does everything and no IT ops org involvement in our AWS cloud deployment.
Who has to ask permission before deploying 100's or 1000's of servers? We don't. The developers use our portal directly, they have to file a Change Management ticket to record what they did if it's in production, that's all. We've trained our developers to operate their own code. We create and destroy up to 1000 servers a day, just pushing new code. AWS takes about 5 minutes to allocate 100 servers, it takes longer than that just to boot Linux on them.
Who has a centralized push cycle and has to wait for the next "train" before they can ship their code? We don't. Every team manages their own release schedule. New code updates frequently, and the pace slows for mature services. Teams are responsible for managing interface evolution and dependencies themselves. Freedom and responsibility again.
Who has project managers tracking deliverables? We don't. The line managers do it themselves. They own the resources and set the context for their teams. They have time to do this because we took the BS out of their role.
Managers have to be great at hiring, technical and hands on enough to architect what their team does, and project manage to deliver results. Don't split this into three people. Reduce management overhead, minimize BS and time wasted. Teams are typically 3-7 people. Have a weekly team meeting and 1on1 with each engineer to maintain context.
Who has a single standard for development tools? We don't. We assume developers already know how to make themselves productive. We provide some common patterns to get new hires started, like Eclipse, IntelliJ, on Mac, Windows. Some people use Emacs on Linux. Hire experienced engineers who care, and they will take care of code quality and standards without being told how to.
Who has to work with people they don't respect? It's much too disruptive. The only way to get high talent density is to get rid of the people who are out of their depth or coasting.
That also applies to what you might call brilliant jerks. Even if they do great work, the culture can't tolerate prima donna anti-social behavior, so people who don't trust others or share what they know don't fit in.
So does that mean we value conformity? No but it's really important to be comfortable as part of a high performance team, so we look for people who naturally over-communicate and have a secure confident personality type.
If you haven't experienced a high performance culture, think about what it's like to drive flat out at a race track. Some people will be too scared to deal with it and drive around white knuckled at 40 mph, some will be overconfident and crash on the first corner, but for people who fit into the high performance culture it's exhilarating to push yourself to go faster each lap, and learn from your peers without a speed limit. When you take out the BS and friction, everyone gets so much more done that productivity, innovation and rapid agile development just happen. This is the key message, removing obstacles to a high performance culture is how innovation happens throughout an organization. Doing less to get more.
We don't pay bonuses. We don't have grades other than senior engineer, manager, director, VP. We don't count the hours or the vacation days, we say "take some". Once a year we revise everyones salary to their peers and current market rate - based on what we are paying now to hire the best people we can find.
We also have what sounds like a crazy stock option plan that grants options every month, vests the same day, and they last 10 years even if you leave Netflix. The net of this is less work for managers, they can concentrate on hiring top people, and almost everyone that leaves takes a pay cut. The test we make is "would you fight to keep your engineers if they tried to leave". If not, let them go now and get someone better. We don't make it hard to let people go.
Some of you may be thinking this sounds expensive, but what is the value of being incredibly productive and able to move faster than your competition? You can get out ahead and establish a leading position before anyone else realizes you are even in the game. Remember how a few years ago the "Analysts" said that Netflix the DVD company was going to get killed by other companies streaming, then all of a sudden people realized that we were streaming more bandwidth than anyone else?
So what could possibly go wrong? We had a near miss recently, we went too fast, partly because we could, got unlucky and screwed up. The good thing is that Netflix could re-plan and execute on the fixes we need very quickly as well, with no internal angst and finger-pointing. Also there was an Asteroid nearby earlier this week. By the way, my stepdaughter @raedioactive was the art director for this movie.
So, you are at a crossroads, you could be on stage with Eric Clapton, or in the audience watching and wondering why you can't do what they are doing. It's a radically different way to construct a corporate culture, it doesn't work for everyone, and we can't all be up on stage with Eric, but the talent is out there if you start by building a culture focused on talent density to find it and keep it.
Is it going to be the goats or the glory? I just told you all to stop doing things, what could be easier than that? It takes less process, fewer rules and simpler principles. Give people freedom, hold them responsible, replace the ones that can't or won't perform in that environment. Focus on talent density and conserving management attention span by removing the BS from their jobs.
This is your challenge, can you get a band together and go on a mission to save your company? Stop doing all the things that are slowing you down, and get rid of the unproductive BS that clogs up your management and engineers.
I will take questions in the comments or on twitter to @adrianco. Thank you.
Each question got a new box shot, but all the answers were musical.
Subscribe to:
Posts (Atom)